Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
The evolution from relational databases to warehouses, lakes, and the Modern Data Warehouse. What each stage solves, what it costs, and why the lake and the warehouse end up as partners, not rivals.
Who is it for?
Data leaders, architects, engineers, and business readers deciding between warehouse, lake, and combined architectures.
The problem: 2 teams, 2 systems, 1 argument
A finance director wants her monthly report from the data warehouse, where the numbers are governed, consistent, and defensible in an audit. A data scientist wants the last 5 years of raw stream data, untouched, so he can experiment with models. The platform team keeps both systems running, but the two camps argue constantly. Finance says the lake is a swamp where nobody can find anything. The data science team says the warehouse is a straitjacket that cost a fortune and still cannot hold a PDF or a streaming event.
Neither is wrong. They are describing two genuinely different storage paradigms, each built to answer a question the previous one could not. The fastest way to stop the argument is to understand the timeline: "Why the warehouse appeared when it did?", "Why the lake appeared 30 years later", and "Why most serious platforms today combine them into something called a Modern Data Warehouse".
Architectures all have a place in a certain use case, no architecture applies to every situation, and everything has trade-offs.
Keep that in mind as each stage of the story gains something and loses something else.
The idea in plain English: a timeline of trade-offs
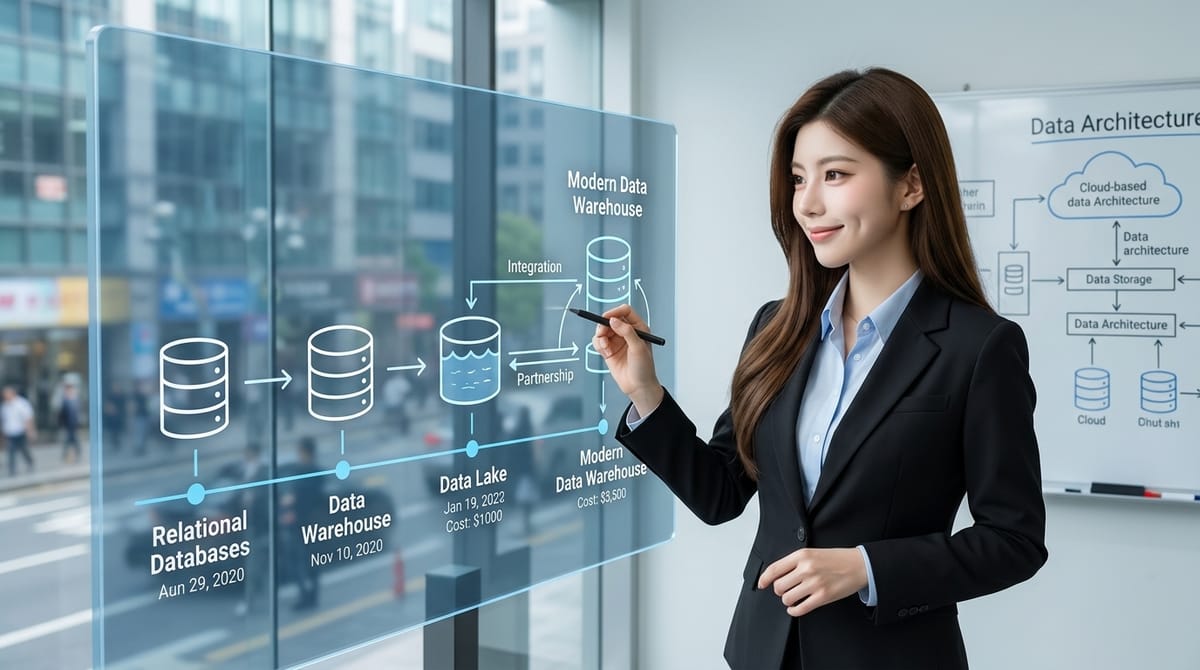
The storage paradigms most organizations juggle today arrived in 4 waves.
Relational databases (RDB / RDBMS) appeared in the 1970s. They store structured data in tables made of rows and columns, related to each other by keys, and they use SQL as the standard language for creating, modifying, and querying data. Their goal is consistency and data integrity, and they achieve it through schema-on-write: the schema, the formal structure of tables, attributes, data types, and constraints, is defined and enforced at the moment data is written. Their home turf is online transaction processing, OLTP, where systems make many fast create, read, update, and delete operations.
Relational data warehouses (RDWH) appeared in 1983. They are a type of relational database designed for something the operational systems were not built for: analytics. Data from multiple operational sources is copied into one central repository, optimized for analytical queries and large-scale analysis, so that users run reports against the warehouse instead of against the systems that keep the business running. This is the world of OLAP.
Data lakes (DL) arrived around 2010. They are simple object storage: no rows and columns required, data kept in its raw, natural format without being transformed. They use schema-on-read, meaning structure is applied only when the data is queried or consumed, not when it is stored. No compute engine is attached; many engines can work with the data.
The Modern Data Warehouse (MDWH), emerged in 2011 and later. It combines the two: a data lake for staging, preparing, and exploring raw data, plus a relational data warehouse for serving, security, and compliance, where business users query and report.
Notice the pattern. Each wave answers the weakness of the one before it, and introduces a weakness of its own. That is the whole story.
How data moves: the ingestion question
The timeline is also a story about where transformation happens, which is where the acronyms ETL and ELT come in.
ETL
In the classic relational warehouse, data moves through ETL: extract, transform, load. Data is extracted from source systems, transformed in flight (cleaned, filtered, aggregated, consolidated), and only then loaded into the warehouse.
An analogy is kitchen preparation: ingredients are prepared before cooking.
The disadvantage is symmetric. Transformation takes time, a bug in the pipeline means going back to the source system to extract everything again, and the transformation engine processes one record at a time with limited support for exotic data types.
ELT
Data lakes flip the order into ELT: extract, load, transform. Data lands in the lake in its raw format first, and transformation happens afterwards, inside the target system, before the data is refined toward its final structure.
The analogy is a restaurant buffet: raw ingredients are available, and diners choose their combinations.
This is the preferred approach for lakes because it supports a wide variety of data types and lets you defer decisions about what matters.
Data virtualization
A 3rd option avoids movement altogether. Data virtualization creates a logical view across disparate sources without copying the data.
The analogy is a library catalog: a central index points to books that stay on their shelves.
It suits real-time access to distributed sources, but it carries considerations of its own: query load lands on the source systems, performance depends on the virtualization engine's optimization, and access control has to be handled in the logical layer.
Reverse ETL
A 4th pattern runs the pipeline backwards. Reverse ETL takes refined, governed results out of the warehouse or lake and loads them back into the operational systems where work happens, so a CRM can act on the segments the analytics platform computed. It matters here because it shows the data journey has two ends, not one.
Batch vs. streaming
Batch versus real-time processing (streaming) cuts across all 4. Data warehouses historically ran on batch: transactions grouped and copied at scheduled intervals, efficient for large volumes, but with delays in availability. Real-time processing (streaming) reacts to each new record as an event, updating the target immediately. It costs more system resources and more complex error handling, which is why it is a choice to make deliberately, not a default.
What the data warehouse is good at
The relational data warehouse earned its decades of dominance for concrete reasons. The benefits still read like a requirements checklist today.
- It reduces stress on production systems, because reports and ad-hoc queries hit the data warehouse instead of the operational databases.
- It is optimized for read access in a write-once, read-many pattern.
- It integrates multiple sources into a single version of truth, eliminating data silos and improving decision making.
- It keeps accurate historical data, restructures and renames tables into a better data model
- It protects reporting against application upgrades
- It supports master data management
- It improves data quality
- It lets business users build reports without involving IT.
Its structure enforces these promises. Schema-on-write means every row conforms before it enters. Transactions, audit trails, and schema enforcement come built in. And decades of modeling tooling exist for it.
What the data warehouse makes harder
Schema-on-write is a straitjacket. You must know your structure before you store anything, which is a poor fit for social media feeds, sensor data, documents, or any source whose value is unclear at ingestion time. Compute and storage are tightly coupled in the classic warehouse, so scaling one means scaling both. And the flexibility cost shows up in price: warehouse compute is the most expensive place to run large transformations.
What the data lake is good at
The data lake answers the warehouse's rigidity. You can store data quickly with no up-front work, in any format, cheaply, at large scale. Data scientists get fast access to raw data for training machine learning models. Investigators can explore data before anyone has decided what it is worth. Because data lands in the lake before being copied elsewhere, the lake can serve as the single point of ingestion and even as the archive: keep the raw history forever and never go back to the source system.
The lake also changes where transformation belongs. Running transformations on the lake instead of the warehouse is cheaper, often faster, offers more ways to refine data, avoids warehouse maintenance windows, and allows querying around the clock.
A lake can turn into a swamp
The lake's weaknesses are the mirror image of its strengths. There is no schema enforcement, no transaction support, no audit trails. Querying raw files is not easy, although newer engines now run SQL directly against lake storage. Data lakes have limited tools for data modeling, while warehouses have had modeling tools for years. And without governance, a lake degrades into a data swamp, where data exists but nobody can find, trust, or use it.
Lake zones (medallions)
This is where lake zones matter. Best practice is to divide the lake into layers of increasing data quality. A raw layer, also called bronze, staging, or landing area, holds events in their original state, immutable and kept for historical reference. Above it sit conformed, cleansed, and presentation layers, arranged as a hierarchy from raw unprocessed data to highly refined business-ready information. The zones are how a lake stays usable instead of becoming a swamp.
Modeling: 3 ways to shape the data
Modeling answers the "how?". Whichever system holds the data, someone has to decide how it is structured for use. 3 modeling approaches dominate.
Relational modeling
Relational modeling is normalized structure, first through 3rd normal form (3NF), focused on data integrity and reduced redundancy. It captures how the business works operationally. It is excellent for transactions and poor for analytics, because a report over a fully normalized model needs a long chain of joins.
Dimensional modeling
Dimensional modeling is built for analytics. It separates facts, the metrics, from dimensions, the context, and arranges them into star schemas, or into snowflake schemas where dimensions are further normalized. It is denormalized deliberately for query performance, easier for business users to understand, and faster to query because it needs fewer joins.
Data vault modeling
Data Vault modeling sits between the two. It uses hubs for business entities, links for relationships, and satellites for attributes. It is designed for historical tracking, lineage, and flexibility, and it supports agile development, which is why many large data warehouses use it as the middle layer and serve dimensional models on top.
Methodology: top-down, bottom-up, or both
Modeling answers "how?"; methodology answers in "what order?".
Top-down approach (Inmon)
The top-down approach, associated with Bill Inmon, is enterprise-wide. You define the enterprise data model first, build a normalized enterprise data warehouse, and create subject-oriented data marts from it. Its benefit is a comprehensive view of data needs, better consistency, and stronger governance. Its cost is time and resources: value arrives later than business stakeholders would like. It suits large organizations with complex data relationships and IT-driven initiatives.
Bottom-up approach (Kimball)
The bottom-up approach, associated with Ralph Kimball, starts from business requirements. You build dimensional data marts with star schemas, then connect them through a bus architecture of conformed dimensions to create a unified view. It delivers quick wins and fits business-driven, iterative development. Its risk is that integration comes late, and consistency depends on the discipline of keeping dimensions conformed.
Hybrid approach
The hybrid approach combines them: a normalized central warehouse built with Inmon's discipline, dimensional marts built with Kimball's method on top, and consistent governance across both. It balances enterprise needs against business agility, at the price of building two layers.
The Modern Data Warehouse: both, deliberately
The Modern Data Warehouse (MDWH) is not a rejection of either paradigm. It is the recognition that the data lake and the data warehouse solve different halves of the same problem and belong in the same architecture.
In an MDWH, the data lake handles staging and preparation: raw data of any format lands there cheaply, transformations run at low cost, and data scientists explore and build models. The relational data warehouse handles serving, security, and compliance: business users query governed, consistent, modeled data. This is ELT in practice: extract and load into the lake, transform in the lake, and serve from the warehouse. Newer MDWH platforms also separate storage from compute, so each can scale on its own.
A small decision guide
Use this to place your own situation on the timeline:
- If your data is structured, your reporting must be auditable, and your users are analysts
- A relational data warehouse, on the classic ETL pattern, may still be the right and proportionate answer.
- If your data is varied in format, arrives before anyone knows its value, or feeds machine learning
- Add a lake with governed zones and ELT.
- If finance, compliance, and self-service reporting all matter alongside exploration
- An MDWH, a data lake plus serving warehouse, is the established combination.
- If a vendor tells you the lake replaces the warehouse, ask "Who serves the governed numbers?", and "Where does the audit trail live?".
- If vendor tell you the warehouse replaces the lake, ask "Where the streams and the documents go?".
- Whichever you choose, decide the modeling approach and the implementation order explicitly. Modeling, integration pattern, and methodology are separate decisions, not one bundle.
2 claims deserve to be retired with the help of this timeline:
- A data lake is not automatically an analytics platform: raw storage without zones, modeling, and governance is a swamp with better marketing.
- A data warehouse is not automatically obsolete: for governed serving, security, and compliance, nothing in the lake world replaces it.
Each belongs to a different part of the journey, and the architectures that follow in this series, the fabric in part 3, the lakehouse in part 4, and the mesh in part 5, all build on the combination rather than on either paradigm alone.
Next
Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
Series
- Your Data Architecture Is a Business Decision, Not a Shopping List
- Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
- Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
- The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
- Data Mesh Is an Operating Model, Not a Tool You Can Install
- Data Architecture Decision Matrix: Choose the Smallest System That Can Work