Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
Data fabric is not a replacement for the modern data warehouse but an added layer for access, security, and discoverability. Value comes only when users can find, understand, and trust data.
Who is it for?
Data leaders, architects, engineers, and product owners deciding whether the extra layer is worth it.
The problem: plenty of data, nobody can find or trust it
Picture a company that has just finished its modern data warehouse (MDWH). Data streams in from operational systems, lands in the data lake, gets cleaned and transformed by a compute engine, and lands in a relational data warehouse (RDWH) where business users build their dashboards. The pipeline works. And still the questions keep coming.
An analyst asks where a customer record actually comes from. A compliance officer asks who may see salary data and who doesn't. A team builds a model and later discovers a second team built the same model on slightly different data. The data warehouse stores everything, but it does not answer who owns a dataset, what it means, whether it is current, or whether you are allowed to use it.
That gap is what the data fabric claims to close. The claim deserves scrutiny, because in vendor language "fabric" can sound like a product that fixes everything. It is something more useful: an evolution of the modern data warehouse (MDWH), not a replacement for it.
The idea in plain English
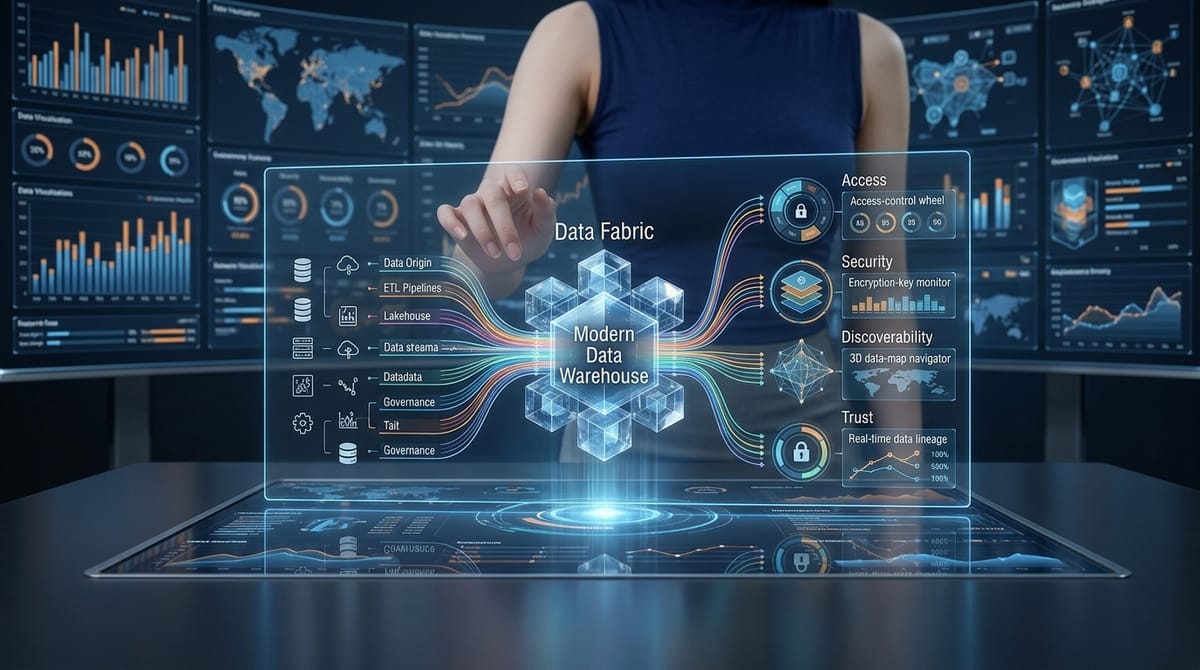
A data fabric contains every component of the modern data warehouse (MDWH) and adds a layer on top of it. That layer exists to improve 3 things the data warehouse itself does not fully deliver: accessibility, security, and discoverability.
The word "adds" matters. If you already operate a modern data warehouse (MDWH) with a lake, a compute engine, and a serving layer, a fabric does not ask you to throw that away. It layers data access policies, a metadata catalog, lineage, master data management (MDM), virtualization, real-time processing, and APIs onto what you have.
The fabric is the most widely used architecture for new solutions handling large amounts of data, with a threshold above 10 terabytes. Treat that figure as context, not a universal law. What it signals is this: the fabric layer is a real cost, and the cost only pays off at a scale where finding, securing, and tracing data has become a genuine problem rather than an occasional annoyance.
How data moves through it
Because a fabric builds on the data warehouse, the data journey stays the same, with one addition. It runs through these stages:
- Ingestion. Data arrives from many sources, structured, semi-structured, or unstructured, in batch or as real-time streams. Architects decide how often to extract and whether each source needs incremental or full pulls.
- Storage. Everything lands in the data lake, the storage hub of the architecture. The lake brings built-in high availability, disaster recovery, security, and encryption.
- Transformation. A compute engine such as Apache Spark or Apache Flink reads files from the conformed layer, cleans, enriches, and consolidates them, writes results back to the cleaned layer, then aggregates for the presentation layer. Storage and transformation stay separate, which is the point.
- Modeling. A relational model, typically 3rd normal form (3NF) or a star schema, is created in the relational data warehouse and data is copied in from the lake. The star schema earns its place through performance and simplicity.
- Visualization. Business users analyze the modeled data in reports and dashboards. There is an exception: new tools make it easy to query and report directly off the lake, so users no longer have to go through the relational warehouse for everything.
- Virtualization. This is the fabric's addition to the journey. A logical layer sits between users and sources, so data spread across the lake, the data warehouse, and other systems can be accessed as if it lived in one place.
- Sandbox. Data scientists also work across this journey in a sandbox layer, a dedicated space for experimentation and exploration that does not affect the other layers, training and building models on raw, cleaned, presentation, or sandbox data as the task requires.
What the added layer actually contains
The fabric's advanced layer has several distinct pieces, and it is worth naming them one by one, because each addresses a different failure.
Data access policies
A set of guidelines, rules, and procedures that control who has access to what information and how it may be used. Every data request must adhere to them. They cover classification, authentication, authorization, encryption, retention, backup, recovery, and disposal, and they support compliance with regulations such as GDPR and HIPAA. In short, the rules of the road get built into the architecture.
Metadata catalog
A central repository that stores information about data assets, their structure, relationships, and characteristics. Its goal is simple: make it easy for users to find and understand data. Without it, discovery happens by asking around, and the answers go stale.
Data lineage
Part of the catalog. It records the history of any piece of data: where it comes from, how it has been transformed, and where it is stored. Lineage is what lets you trace an error back to its source, or satisfy a regulator who asks exactly how a reported number was produced.
Master data management (MDM)
Master data is the non-transactional data that describes key entities: customers, products, suppliers. MDM collects, consolidates, and maintains it from multiple sources into a single authoritative version, avoiding duplicate records and inconsistencies. It is unglamorous, often slow work, and it is the difference between two departments agreeing on what "customer" means.
Data virtualization
Access data from multiple sources as if it were stored in a single location, through a logical layer acting as intermediary between users and sources. It reduces copying, though it does not remove the need for good storage underneath.
Real-time processing
Producing immediate results so decisions rest on up-to-date information rather than last night's batch.
APIs
A standardized way to serve data from the lake and the warehouse without exposing where the data physically lives. Consumers integrate against an interface, not a location.
What it is good at
The modern data warehouse (MDWH) underneath already delivers a lot, and the fabric keeps all of it. The warehouse handles any data type from any source, separates storage from compute so you can pick formats like Parquet and engines like Spark or Flink independently, scales with the business, supports real-time analytics, serves fast concurrent queries through MPP (massive parallel processing) technology in the relational layer, and enables self-service business intelligence.
The fabric adds what the warehouse could not: a uniform answer to "What data exists?", "What does it mean?", "Who may use it?", and "Where did it come from?". For organizations with many teams, many sources, and regulatory exposure, that uniform answer is not a luxury. It is what keeps the warehouse from slowly decaying into a well-fed collection of silos.
We need to be direct about one of the warehouse's risks: without governance, a modern data warehouse (MDWH) leads to data silos. The fabric layer is essentially the governance response to that risk.
What it makes harder
More components mean more to build, run, and staff. Implementation and management of a modern data warehouse (MDWH) are already complex; the fabric layer adds catalogs to populate, policies to write and enforce, MDM programs to sustain, and virtualization layers to operate. Setup, maintenance, and scaling all cost money. And the skills requirement is real: a fabric demands even more of it.
There is also a subtler risk. A metadata catalog that nobody maintains is worse than no catalog, because it lends false confidence. Access policies that exist in a document but are not enforced in the platform are paperwork, not governance. The fabric's tools only work when someone feeds and enforces them.
People, process, and governance implications
Governance is usually drawn as a final stage: build the pipeline, then bolt on controls before launch. The fabric's message is the opposite. Access policies, catalog, and lineage are part of the architecture itself, decided when you design ingestion and storage, not documented after the fact. If you decide later where the catalog entries and lineage capture come from, you will retro-fit them at high cost, or not at all.
People decide whether self-service becomes real. The warehouse promises that users can build their own reports and dashboards, but a user can only self-serve what they can find, understand, and access. That depends on data engineers who keep lineage current, stewards who classify data, and an MDM effort that someone actually owns. The principle stands: architecture that nobody can operate is not a successful architecture.
A practical starting point: give one team explicit ownership of the catalog and access policies from day one. A fabric layer without an owner becomes shelfware.
A small decision guide
Choose the modern data warehouse (MDWH) baseline when you need lake flexibility plus governed serving, and your discovery and access questions can still be handled by convention and a small team.
Add the fabric layer when at least 2 of these are true:
- Many teams consume the same data
- Regulators demand traceability (GDPR or HIPAA exposure is a clear signal)
- Duplicated or inconsistent master records are causing real disputes
- Users regularly cannot find data without asking someone.
When in doubt, stage it. Most organizations can introduce the components separately: a catalog first, then lineage, then enforced access policies, then virtualization where copying hurts. A fabric does not have to arrive in one go.
And keep the skepticism handy. The >10 TB figure is the context for where fabrics are most widely used for new solutions, not a gate. A 4 TB estate with heavy regulation can need the fabric layer more than a 40 TB estate with 3 users. Volume is a proxy for the real question: "Has finding, securing, and tracing data become a bottleneck?"
Next
The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
Series
- Your Data Architecture Is a Business Decision, Not a Shopping List
- Data Warehouse, Data Lake, or Both? The Architecture Timeline That Makes It Clear
- Data Fabric Is Not Magic: What It Adds to a Modern Data Warehouse
- The Data Lakehouse Promise: One Repository, Fewer Pipelines, New Trade-offs
- Data Mesh Is an Operating Model, Not a Tool You Can Install
- Data Architecture Decision Matrix: Choose the Smallest System That Can Work