Evolutionary Blueprint (8). When curiosity becomes a reward, what does an AI explore?
Series: Evolutionary Blueprint of AI, article 8. An exploration bonus can help an AI find useful experiences when task rewards are scarce. See how prediction error works, why random noise can hijack it, and how to test exploration without exposing customers or systems to unnecessary risk.
Who should read it?
Business and technology leaders, product teams and curious non-specialists.
Metapher
The unexplored frontier
Intro
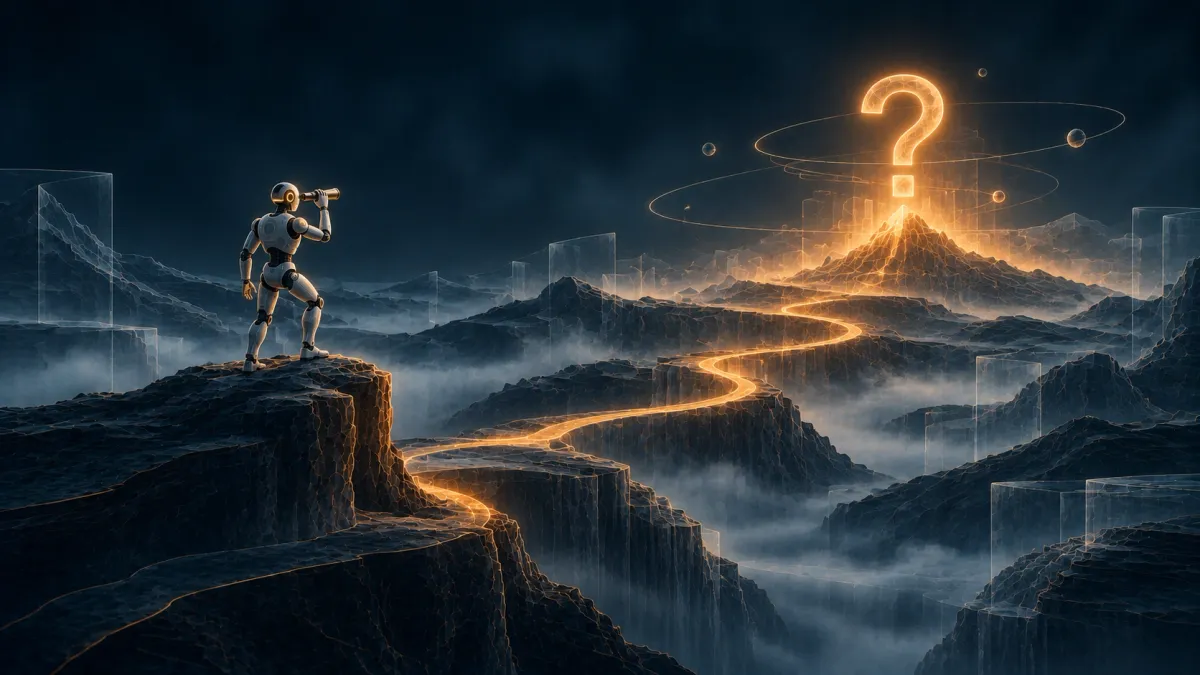
A warehouse wants to teach a robot to move parcels without blocking a loading bay. In a simulator, the robot earns a task reward when it delivers a parcel to the right station. At first, it rarely succeeds. It may spend most of its time circling near the starting point, receiving little feedback about which movements could lead to a delivery.
One way to change its behavior is to reward it for encountering outcomes it did not predict well. This is a computational training signal, not evidence that the robot feels curiosity as a person might. Depending on how training updates its action policy, it might try a different route, stare at a flickering screen or repeatedly cause a simulated collision. The bonus alone does not choose among those outcomes.
The warehouse is a fictional example, not a reported deployment. It brings the final core topic into focus:
- Exploration can produce useful experience before a task pays off, but surprise is not the same as progress
The biological comparison is a source of questions for engineering, not evidence that brains and AI use the same algorithm.
Exploring can reveal routes a familiar policy misses
Exploration means trying actions whose consequences are uncertain. Exploitation means choosing an action that appears best according to what the system has learned so far. A delivery robot that always takes its familiar route exploits its current knowledge. A robot that tests a different permitted route explores.
Exploration has a cost. A new route may be slower, and in a real warehouse it could put people or equipment at risk. Avoiding all exploration also has a cost: the robot may never discover a route that works better when the usual aisle is blocked. The right balance depends on the task and the consequences, not on a universal percentage of random actions.
Random actions are one way to explore, but they are not the only way. An agent can also be encouraged to visit unfamiliar states or seek experiences that its predictive model handles poorly. The aim is to collect informative experience, not simply make the robot behave unpredictably.
Animals explore, but the analogy has limits
A puppy may investigate an unfamiliar object without receiving food for doing so. Such behavior can give an animal experience that later proves useful, although observing an action alone does not reveal its complete motivation or prove a particular evolutionary purpose. Play and exploration overlap, but they are not identical.
Nor are they exclusive to mammals. In a 2017 study, Megan Lambert and colleagues let New Caledonian crows explore objects before a tool-selection task. Several birds performed above chance after exploration but not in a comparable condition without it. The authors did not find evidence that the birds changed their exploration strategically to seek task-relevant information. This is a specific experiment with birds, not a demonstration that all exploration has the same purpose.
In psychology, intrinsic motivation often describes engaging in an activity for its own sake rather than for a separable external payoff. In reinforcement learning, an intrinsic reward is a computational signal generated inside the learning system, such as a bonus for a surprising observation. Engineers choose or design the mechanism that produces it. Calling the signal "curiosity" describes its role in training; it does not establish that the agent feels interest, boredom or any other subjective experience. An agent can also remain a tool even when it selects actions without a person choosing each one.
Prediction error supplies one kind of bonus
A reinforcement-learning agent takes an action, observes what happens and uses reward signals to adjust its future behavior. The task reward represents an externally specified objective, such as successful delivery. When that reward is rare, an additional intrinsic reward can give the agent feedback along the way.
A prediction-error bonus works like this
- The agent observes its current situation and selects an action.
- A learned predictive model estimates what the next observation will be after that action.
- The agent observes the outcome and measures the difference from the prediction. That difference is the prediction error.
- The training process assigns an intrinsic bonus based on that error, alongside any task reward. Over repeated experience, the agent's action-selection policy and predictive model can be updated.
The bonus is not a label saying the action was beneficial. It is a training signal that can make transitions with higher measured error attractive. As the predictor learns a repeatable transition, its error and bonus may fall. They need not fall if the outcome is random, the model is inadequate or the agent cannot observe enough of the situation.
The specific implementation matters. Deepak Pathak and colleagues' 2017 study measured prediction error in a learned representation of visual observations, rather than treating every pixel as equally relevant. They evaluated the method in VizDoom and Super Mario Bros. and reported better exploration in the settings they studied, including a sparse-reward setting. Those game results support the approach as a research technique; they do not guarantee faster or safer learning in a warehouse.
Prediction error is also only one route to intrinsic reward. Counting visits to states, for example, gives a system a different way to favor less-visited situations. An implementation should be judged by the experience it generates and the task it improves, not by whether its designers call it curiosity.
Follow the robot through a simulated shift
Return to the fictional warehouse. The team's simulator contains two aisles, a loading station and virtual parcels. The robot's task reward comes only when a parcel reaches its assigned station. The team also gives it a prediction-error bonus for differences between predicted and observed position, parcel state and nearby obstacles. These are illustrative design choices, not results from the cited studies.
On its first simulated run, the robot expects to travel down the familiar aisle, but a movable cart blocks the route. The predicted outcome was forward progress. The observed outcome is a stop. That mismatch earns a bonus. The training system records the transition, and the predictive model can learn that a cart in that position blocks movement. The bonus does not directly teach the alternate route:
- It rewards the surprising stop
How the action-selection policy is updated determines what the robot is more likely to do next. It might repeat the stop, or explore the other permitted aisle and eventually reach the station for the task reward.
This sequence makes the distinction visible. The intrinsic bonus rewards the mismatch, not the delivery. If the model learns the blocked-cart transition, repeating that same predictable stop may provide a smaller bonus. The alternate aisle can be useful because it leads to delivery, not merely because it was unfamiliar. Exploration does not guarantee that the agent will choose it or that learning will proceed in this neat order; the sequence is an illustration of what the team hopes to encourage and then test.
Now change the simulator. A display beside the starting point shows a random pattern. If the bonus is based on every pixel, the robot may earn a high score by staying near the display because the next pattern remains hard to predict. It can accumulate surprise without learning a better route or delivering a parcel. If a collision creates an unpredictable pile of moving objects, repeated collisions could create the same incentive while causing damage in the real world.
A team can reduce the first problem by limiting the predicted features to information relevant to movement and delivery. To address the second, an independent safety controller can prohibit a dangerous movement before execution. A collision penalty instead reduces reward after a collision. It discourages the behavior but cannot guarantee prevention. Neither approach automatically solves exploration: an omitted feature may matter, a simulator may model a hazard badly, and the agent may find another way to collect an unhelpful bonus.
The noisy TV exposes a failure of surprise
Researchers call the random-display trap the noisy TV problem. Yuri Burda and colleagues studied prediction-based curiosity across simulated environments and tested a maze containing a television that changed randomly. In their experiment, the television substantially slowed learning. The paper also notes that some agents eventually learned to obtain the external reward when given enough time. The finding is a warning about a particular failure mode, not a claim that every curiosity method always gets stuck.
The problem is that error has several possible causes. A robot may be surprised because it has not learned a route yet, because a sensor is noisy, because an event is genuinely random, or because an important variable is hidden. More experience can resolve the first kind of uncertainty; it may do little for the others. Paying for error alone does not tell the agent which situation it has encountered.
One alternative is to reward disagreement among several predictive models, rather than raw error. Deepak Pathak, Dhiraj Gandhi and Abhinav Gupta investigated this approach in simulated benchmarks and a robot experiment, including stochastic settings. Disagreement can be a useful signal of what the models have yet to learn, but it is not a safety guarantee or a universal solution to noisy observations. Teams still need to test how their particular models behave.
Put boundaries around the learning, not just the task
For a business considering an exploratory agent, the first decision is whether the uncertainty is worth investigating at all. A robot routing experiment may justify a simulator and controlled trials. A routine customer email classifier may be better served by labeled examples and human review. Not every product needs an agent that explores.
If exploration is appropriate, assign a process owner and define an independent business outcome before choosing a bonus. In the warehouse example, measure successful deliveries on representative held-out scenarios: warehouse situations kept out of training and used only for evaluation. Measure collisions and blocked-aisle recovery separately. Compare the curiosity-trained policy with a baseline trained on task reward and a specified exploration method, such as occasional random permitted actions. Give both the same training budget, simulator conditions and safety restrictions, then evaluate both on the same held-out scenarios. Track bonus collected separately:
- A rising curiosity score is not proof of better delivery performance
Train in an isolated simulator first, using synthetic or appropriately protected data. Add scenarios with blocked routes, sensor faults and unpredictable displays. Limit the agent's permitted actions, set resource and time budgets, log decisions and outcomes, and give an operator a clear stop mechanism. A simulation can miss real hazards, so a successful virtual run is a reason to plan a controlled evaluation, not permission for unrestricted deployment around people.
The same boundary applies to other domains. A cybersecurity agent should probe only systems for which the organization has explicit authorization, within a documented scope and rate limits. Novelty does not justify touching a production service or a third party's network. A proposed probe that could disrupt operations should require human approval or remain in an isolated test environment. The more costly an action, the stronger the case for hard limits outside the agent's reward function.
More surprise does not necessarily mean better learning
An intrinsic reward can help an agent encounter experiences that a sparse task reward would not guide it toward. Prediction error is one possible bonus, not a measure of conscious curiosity or a promise of useful learning. Before putting exploration to work, define success independently, test against a baseline, watch for rewards generated by noise, and restrict what the agent can do while it learns.
Previous
Article 7: 5 ways to think about intelligence