Offline Is Not Enough: What It Really Takes to Make a Local Model GDPR Compliant
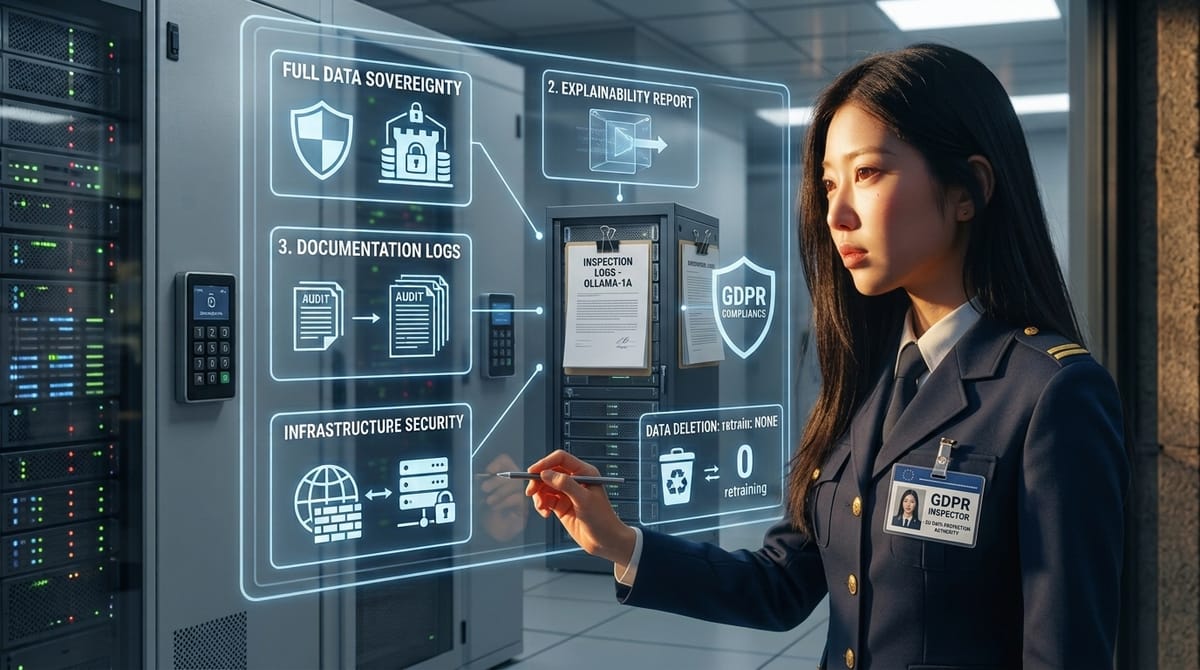
Running Ollama on your own hardware removes the biggest single GDPR risk, the transfer of personal data to an external API. It does not make you compliant. 5 more steps carry the rest: full data sovereignty, explainability, documentation, infrastructure security, and deletion without retraining.
Who should read it?
Teams deploying local LLMs for personal-data workloads, IT leads who approved the GPU purchase and now get the compliance question.
Sibling article
- Papers, Please: Documenting the AI Lifecycle for EU AI Act Compliance
Intro
Your company buys 2 GPU servers, installs Ollama, points the internal tools at localhost, and declares the GDPR problem solved. After all, no personal data crosses the internet anymore. No 3rd-party processor, no transfer outside the EU, no OpenAI subprocessor chain to audit.
That argument is correct, and it covers roughly one-fifth of what compliance actually requires. Local inference eliminates the data-transfer risk, which is real and which keeps many projects in legal limbo. But the GDPR does not grade you on data transfer alone. It asks whether you can explain automated decisions, prove what your system knows and where it learned it, secure the infrastructure against attacks that did not exist three years ago, and delete a person's data on request without retraining anything. A locally hosted model can fail every one of those tests just as badly as a cloud one.
Here are the 5 steps that turn "runs offline" into "defensibly compliant".
Step 1: Total data sovereignty, not just local inference
The first step is the one most teams have already half-done, but the half matters. Personal data must never leave infrastructure you control, and that includes the parts of the stack people forget.
Running a model with Ollama or LM Studio on your own hardware, a Mac Studio in the office or a GPU server in your own rack, removes the primary exposure: no query containing customer names, contract texts, or support tickets goes to a third-party processor. If you use open-weight models with non-EU origins, self-hosting is also the safer route compared to their public APIs, precisely because you avoid sending anything through a hosting provider whose data handling you would have to verify.
The forgotten leak is the tooling around the model. Many local AI stacks include a web search layer, often SearXNG, so the assistant can look things up. If that layer is not hosted locally, every query the model formulates travels to external public APIs, and those queries are constructed from your users' input, which frequently contains personal data. A SearXNG instance you run yourself, in Docker, on the same infrastructure, closes that path. Sovereignty is a property of the whole pipeline, not of the model file.
The practical check is blunt: trace every network call your stack makes during a typical session. Anything that leaves your controlled environment while carrying user input is a finding.
Step 2: Explainability, or the right to an explanation
GDPR gives individuals rights around automated decision-making, but the scope needs care. Article 22 applies to decisions based solely on automated processing that have legal or similarly significant effects on a person; a chat assistant answering questions usually falls outside it. And even inside that scope, a general "right to an explanation" is contested among lawyers; what the regulation clearly demands is meaningful information about the logic involved. Black-box behavior is a problem under both regimes nonetheless: GDPR through its transparency and accountability duties, the EU AI Act through its risk classification. Local hosting changes nothing here: the model knows no more about its own reasoning just because it sits in your basement.
SHAP (SHapley Additive exPlanations) and LIME quantify which input features influenced a specific output, which lets you answer "Why did the system decide this?" with something better than a shrug. A direct caveat, and not a small one: both were built for classifiers with discrete input features, not for a language model generating free text. Applying them to an LLM requires real adaptation, and for generative outputs the "explanation" question often has to be answered through output auditing and process documentation instead of feature attributions. The obligation is real; the tooling transfers only partially. On top of that, counterfactual testing probes the model for reliance on protected characteristics: change the user's age, gender, or ethnicity in the input and check whether the output changes. If flipping a protected attribute flips the decision, you have found discrimination baked into behavior, and you found it before a regulator did.
The practical test is simple and uncomfortable: ask the system to explain a recent real decision, in the terms a data subject would understand. If the answer your team can produce is "we ran a prompt," that is the black-box finding, whatever the hosting situation.
Step 3: Documentation, the step nobody is excited about
Compliance that cannot be demonstrated is compliance that does not exist, under both GDPR's accountability principle and the EU AI Act's documentation duties. 3 records matter:
- Data lineage
- Document the source of every dataset used for fine-tuning or fed into your RAG index, and confirm you hold the legal right to use it. If you cannot confirm that personal data was scrubbed from a fine-tuning set, that is a compliance risk sitting in your weights.
- Model lifecycle
- Keep records of model version, training parameters, and updates. This is where local deployment hides a trap. If you fine-tune a general-purpose model and change its capabilities or intended purpose, the EU AI Act treats you as the "provider," and its documentation and risk-assessment duties pass to you from the original trainer. Free weights plus a training run equals obligations.
- Systemic risk
- If your stack relies on powerful general-purpose AI (GPAI) models, those trained with more than 10^25 FLOPs carry a presumption of "systemic risk" under the EU AI Act (the Commission can also designate capable models below that line), and the provider must document ongoing adversarial testing and risk assessments. If you are the provider after fine-tuning, that documentation burden lands on you. Most teams self-hosting a 7B model are nowhere near this threshold, but the check costs 5 minutes and settles the question permanently. The provider-side documentation duty itself, the full lifecycle record, is the subject of the companion piece "Papers, Please" on AI Act documentation; this article stays on what GDPR expects of a local deployment.
Step 4: Secure the infrastructure, the ENISA multilayer framework
GDPR requires "appropriate technical and organizational measures" to protect personal data. For AI systems, the European Union Agency for Cybersecurity (ENISA) publishes a multilayer framework that maps well onto a local deployment, in three layers. Worth being precise about its status: ENISA is a security reference and good-practice guide, not law. It informs how you satisfy GDPR's security-of-processing duty (Art. 32) and how you evidence AI Act security measures; it carries no obligations of its own.
- Layer 1, IT security basics
- The server hosting your model is a server. Zero-trust architecture, access controls, vulnerability management, patching. If an attacker gets shell access to the inference box, they get everything the model has ever processed, plus the vector index.
- Layer 2, AI-specific threats
- Local and cloud models face attacks that conventional software does not.
- Data poisoning manipulates the documents your model reads, most concretely the corpus you fine-tune on or the files indexed for RAG, so an attacker who can insert a document into that pipeline can steer the model's answers.
- Adversarial attacks are inputs crafted to force errors or extract behavior you did not intend. A locally hosted model is not protected from these by being offline; if anything, your RAG corpus becomes the most attractive attack surface in the building.
- Layer 3, sector-specific layers
- Healthcare and finance carry stricter requirements, audit trails and fail-safe plans, and a local deployment in those sectors must meet them on top of the base layers.
Step 5: The right to be forgotten, which is an architecture decision
GDPR's right to erasure is the step with the deepest design consequence, and the decision belongs in the architecture phase, not the incident-response plan.
If personal data was baked into the model weights through fine-tuning, deleting it means either proving the weights have "forgotten" (there is no reliable, accepted way to do that) or retraining. Both are expensive and neither is instant.
Favour retrieval-augmented generation (RAG) over fine-tuning
The superior pattern is retrieval-augmented generation over fine-tuning: knowledge lives in a local vector index such as FAISS, and the model stays frozen. When a user exercises the right to be forgotten, you delete their documents from the index and the deletion is complete immediately. No retraining, no uncertainty about what the model "still knows," no retention argument.
One condition to state honestly: this holds only while the frozen-weights assumption actually holds in your stack, meaning no fine-tuning runs that folded indexed material into the weights, and prompt caches or conversation logs treated as personal data with their own deletion path. The same separation gives you versioned, auditable knowledge: you can show exactly what was in the index on any given day.
This is the strongest argument for RAG as the default architecture for anything touching personal data, and it is an argument that exists only for local deployments, because a local index is one you actually control. The privacy upside of that same architecture, layer by layer, is the subject of the companion piece on local semantic search.
The checklist
| Step | Action |
|---|---|
| 1. Isolate data | Local hosting (Ollama, Docker) with no external API calls anywhere in the pipeline, including the SearXNG search layer. |
| 2. Explain decisions | Apply XAI tooling (SHAP/LIME) and counterfactual tests; document adapted methods for generative outputs. |
| 3. Document everything | Data lineage for fine-tuning and RAG, model lifecycle records, GPAI risk assessments where thresholds apply. |
| 4. Secure the stack | ENISA multilayer framework: zero-trust IT basics, data-poisoning and adversarial-attack defenses, sector-specific layers. |
| 5. Enable deletion | RAG over fine-tuning, data in a local vector index (FAISS), so erasure is instant and the model stays frozen. |
What to do with this
- Run a network trace on your local AI stack during a realistic session; classify every outbound call.
- Decide RAG vs. fine-tuning explicitly for any personal-data use case, and document the decision; default to RAG.
- Assign the 3 documentation records (data lineage, lifecycle, risk assessment) to named owners before the first real workload lands.
The GPU servers were step one. Steps 2 - 5 are cheaper today than after the first erasure request.