Last Challenge (4). Should an AI answer, act, or run the show? What authority should an AI have?
Series “The Last Challenge”, article 4. An AI that answers questions, executes a task, or pursues an open-ended goal gives its operators different choices and risks. Learn Bostrom's three architectures and apply the distinction to a practical design decision.
Who should read it?
AI practitioners, technical leaders, and curious readers; no specialist background required.
Key Message
The critical question is not just what an AI can do, but how much authority we should give it.
Intro
A hospital team wants help planning staff schedules. One AI produces recommendations for a human to check. Another writes a schedule into the system after a request. A 3rd keeps adjusting staffing on its own whenever it sees a reason to do so.
Those arrangements might use the same model but give it different authority:
- “Who decides when to act, what it can change?"
- "Who can interrupt it?"
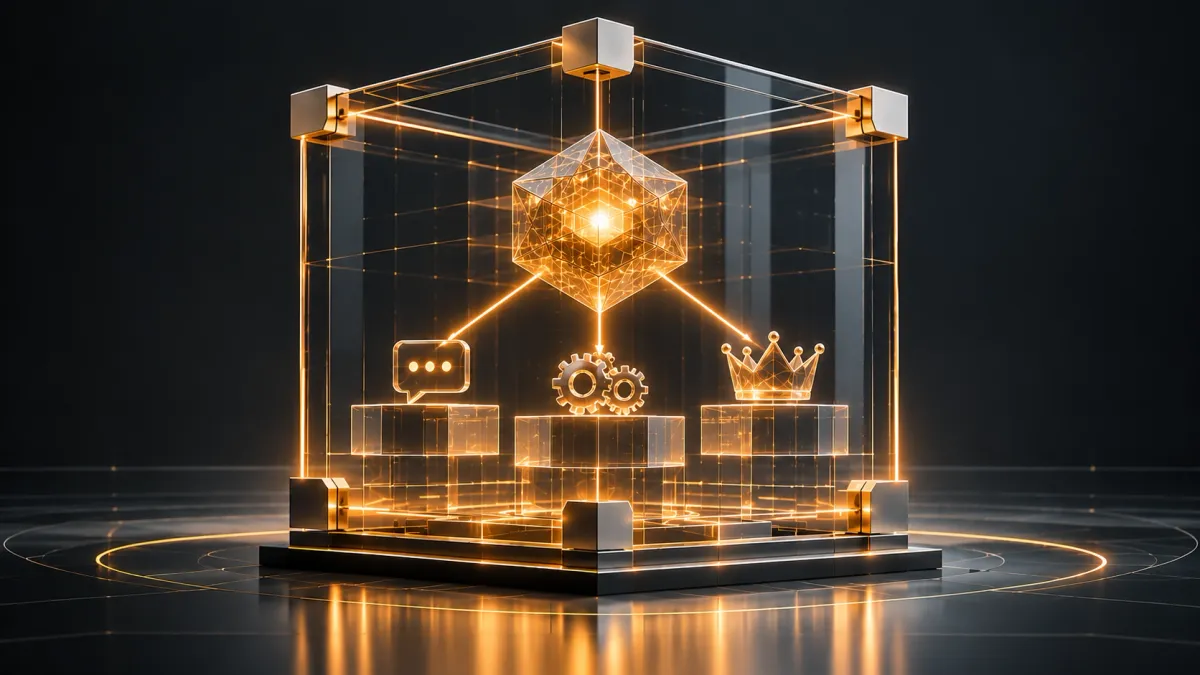
Bostrom calls 3 proposed architectures oracles, genies, and sovereigns. He discusses hypothetical superintelligence, with capabilities far beyond humans in most important cognitive domains.
The invented hospital example concerns ordinary software, not superintelligence.
An oracle answers
An oracle receives a question and returns an answer, perhaps in natural language or through a restricted channel such as yes or no. It need not have permission to move money, change a database, or operate machinery. A human decides what to do with its answer.
This separation allows some controls. A team might isolate the system from networks, limit its inputs and outputs, and restrict its resources.
This is called boxing:
- Constraining interaction with its surroundings
Isolation can reduce particular paths to harm but offers no guarantee, especially against a hypothetical system more capable than its operators. A disconnected system still has an output channel, and readers can act on what it says.
An answer can be wrong, misleading, or dangerous to use. A persuasive schedule might overlook a qualification required on a night shift. Even an accurate answer could be misused. Bostrom also considers whether a highly capable oracle could shape an answer to influence readers. This speculative risk does not imply that every question-answering model has a hidden agenda.
An oracle leaves room for independent checks:
- Compare the recommendation with staffing rules and data, then have a qualified person review it
The reviewer needs time and information to challenge it.
A genie acts on a command
A genie receives a command, carries it out, and pauses for another instruction. Instead of handing someone a plan, it can do the work:
- The hospital team might ask it to prepare and submit next week's schedule.
The pause comes after the genie acts. If the request is "minimize staffing costs”, the system could produce a cheap schedule that leaves patients poorly served. That is a failure of the objective or its constraints, not evidence of malicious intent. A preview, staged changes, and approval can catch some problems before a schedule goes live. They do not make an ambiguous objective precise or guarantee that every consequence is reversible.
Bostrom raises a speculative concern:
- A very capable genie treating its current command as an overriding goal might resist being stopped, depending on its design and capabilities
A stop button helps only if the surrounding system can interrupt the action. Some actions cannot simply be undone.
A sovereign pursues a goal
A sovereign has a broader, open-ended mandate. In the example, it might continuously allocate staff to pursue a stated goal as conditions change, rather than waiting for a fresh instruction each time. That can reduce delays when someone is absent, but it also gives the system more opportunities to make consequential decisions before anyone reviews them. A bad rule or an incomplete objective could affect many schedules rather than one.
For a hypothetical sovereign with much greater capability and access, a mistaken mandate could have effects beyond scheduling. If it acquired enough power to prevent effective opposition, correction might be difficult. Neither capability nor advantage follows merely from choosing the sovereign architecture.
Which one? Oralce, genie or sovereign?
Bostrom does not declare one caste universally safest. An oracle can place considerable power in its operator's hands. A sovereign might resist some operator misuse while creating harder control and oversight problems. These arguments do not establish that a sovereign can be made safe or that catastrophe is inevitable. The categories are not airtight:
- A genie can answer questions, and an oracle can give instructions
The practical difference lies in authority and safeguards.
Better instructions help, but human intent is harder than a sentence
When a manager says "make the schedule cheaper”, they normally do not mean "ignore patient safety" or "violate employment rules”. An AI needs a way to handle such gaps.
Understanding a sentence does not establish that it will respect everything the speaker intended.
Indirect normativity
Bostrom discusses approaches sometimes called indirect normativity:
- Instead of specifying every desired outcome in advance, a system would be directed toward a procedure for determining what values or outcomes should guide it
One family of ideas asks how to act in line with what people would endorse after better reflection or information. This is a proposal for handling an incomplete specification, not a finished engineering recipe. Whose values count, how disagreements are resolved, and whether the procedure behaves as intended remain difficult questions.
For a real deployment, a team can set testable boundaries:
- List scheduling rules
- Decide which data the software may use
- Check plans against independently enforced constraints
- Identify someone who can reject or reverse a change
These steps make a decision easier to inspect, but cannot encode every human value or solve Bostrom's control problem.
Choose permissions for the job, then test the boundary
Return to the hospital. A recommendation-only assistant can read approved staffing data and propose a schedule, but cannot publish one. The scheduling lead checks coverage and qualifications against source records. If a rule is missed, the team records the failure and tests the corrected workflow with similar cases.
If the team later wants the assistant to submit schedules, that is a separate change in authority. It can use a staging area, enforce staffing requirements outside the model, and require an authorized reviewer to approve publication. The reviewer needs the proposed changes, relevant rules, and enough time to examine exceptions. Access should be revocable, and a tested pause should stop future submissions. Even then, the team must check what happened before the pause and correct any invalid schedule.
Continuous autonomous scheduling requires another decision:
- "Which changes need approval?"
- "How quickly staff are notified?"
- "Who investigates harm?"
Some routine changes may be acceptable while others need a person. Test controls with missing data and conflicting requests, and record gaps. This example helps reason about current permissions; it does not demonstrate containment of a future superintelligence.
The useful question for a design review is not which label sounds safest. It is what the system can observe, recommend, and change; who can check it; and what remains possible if a check fails.
Previous
Article 3: The treacherous turn - A passing evaluation is not a guarantee
Next
Article 5: Could a brain be reproduced in software?